
Seamless ML Model Deployment & AI Optimization
Deploy Your AI Models
The platforms and clients we build with
Certified across the major clouds and trusted by enterprise teams to deliver AI that reaches production.
Deliver scalable, efficient, and reliable AI systems with optimized performance and seamless deployment workflows
Lower Operational Costs
Reduce cloud costs through optimized infrastructure and resource usage
High-Performance APIs
Deliver fast, low-latency responses for real-time applications
Scalable Infrastructure
Handle increasing workloads with auto-scaling systems
Automated CI/CD Pipelines
Enable seamless model updates and version control through automated MLOps pipelines
Reliable System Performance
Ensure high uptime with monitoring and failover mechanisms
Faster Time to Production
Deploy models quickly from development to production
Solving AI Deployment and Integration Challenges
We help organizations overcome challenges in understanding, processing, and scaling communication across systems and teams.
Inefficient API Performance
Slow response times impact user experience and system efficiency.
High-Performance Inference APIsModel Performance Drift
Model accuracy declines as real-world data evolves.
Continuous Monitoring & RetrainingDeployment Complexity
Moving models from development to production is risky and inconsistent.
Containerized Deployment & MLOpsScaling AI Systems
Handling high traffic and workloads becomes difficult without proper architecture.
Auto-Scaling InfrastructureHigh Cloud Costs
Inefficient resource usage increases operational expenses.
Resource Optimization & Cost ControlLack of System Visibility
Limited monitoring makes it difficult to track performance and issues.
Real-Time ObservabilityOur Approach
We follow a structured approach to optimize, deploy, and scale AI systems for performance, reliability, and efficiency.
Analyze architecture and identify performance bottlenecks.
Optimize backend processing and request handling.
Implement CI/CD pipelines for deployment automation.
Deploy systems with auto-scaling infrastructure.
Continuously track performance and improve efficiency.
Trusted by enterprise leaders
What decision-makers say about working with Techverx.

We worked with Techverx on the development of an application. Their team took on the task as though it was being developed for themselves. Their expertise, support and contributions were very key to the success. Techverx continues to be involved in further development for our company. I highly recommend their services.
 Director Information Technology — Postal Methods
We reached out to Techverx in March 2019 and asked them to provide us with a proof of concept for a new subsystem that we were building. They rose to challenge and delivered a great POC in the four week timeframe. Since, that time Techverx has been a great partner for us. They are an integral part of both our architecture and development teams.
 Head of Engineering — Lightpoint
Working with Techverx has been a great collaboration is more than an understatement. They are engaging, interactive and futuristic. The inhouse support is always there around the clock to keep us updated about the process.
 Head of Product Management — Drive
Techverx got us from a stuck pilot to a governed production system in a single quarter — they understood compliance as well as engineering.
Recent work, from concept to production
A look at systems we've designed, built, and shipped — with the outcomes they moved.
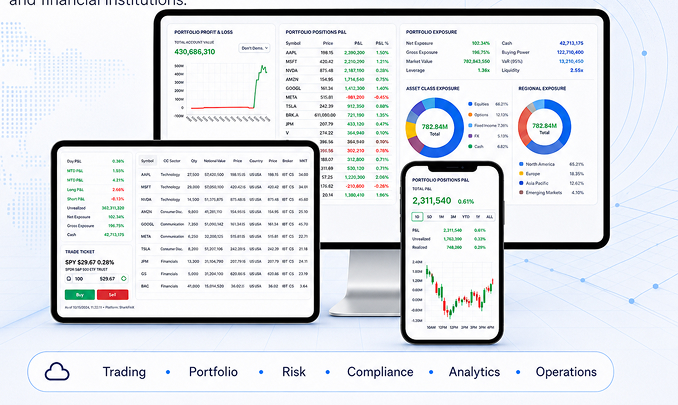
Modern FinTech Infrastructure for Trading and Operations
SharkFin is a cloud-based SaaS platform for hedge funds, family offices, and financial institutions, providing integrated trading, portfolio, risk, compliance, analytics, and operations capabilities.
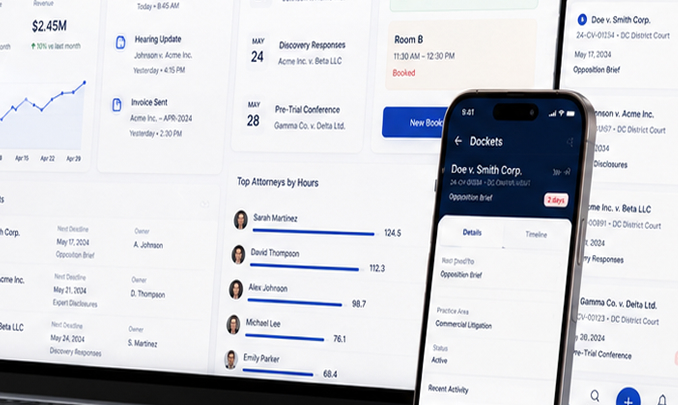

Future-Ready Banking Infrastructure for BMO Financial Group
BMO Financial Group is one of North America's leading financial institutions, serving millions of customers through a wide range of banking and financial services.
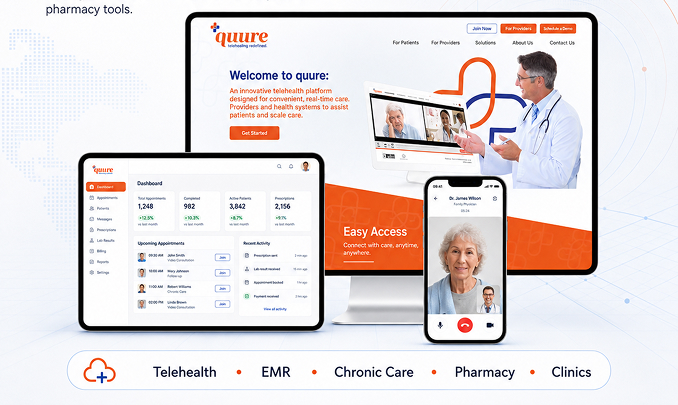
A SaaS based telehealth platform for clinics
Quure is an innovative telehealth platform designed to unify complex healthcare services through a single interface. It integrates EMR, chronic disease management, and pharmacy tools.
Outcomes that drive growth, efficiency, and innovation
Improve performance, reduce costs, and scale AI systems efficiently with optimized deployment strategies.
Lower Cloud Costs
Average API Latency
System Uptime
Traffic Handling Capacity
Proven tools, chosen for the problem
We use established technologies, frameworks, and machine learning tooling to deliver high-performing, custom AI systems across industries.
Models, pipelines and stores
Cloud & deployment
Application layer
Interfaces & BI
Keep reading
Frequently asked questions
The answers to your questions